GitHub Actions Self-Hosted Runners: Secure Architecture and Autoscaling Patterns

Content authorBy Irina BaghdyanPublished onReading time13 min read
Business team viewing a digital technology network and interconnected data systems in a modern corporate environment

Self-hosted GitHub Actions runners give teams control over cost and environment, but they also put build infrastructure inside the trust boundary, where a single compromised workflow can reach internal systems. A defensible architecture starts by naming the threats runners introduce, then applies controls that contain them: ephemeral runners, default-deny network isolation, and short-lived workload identity in place of stored cloud credentials. Scaling models sized to real demand keep capacity honest rather than padded. A cost model and a migration path off persistent runners complete the case, laid out so engineering and finance can review and approve it in a single meeting.

GitHub Actions self-hosted runners

Most teams reach for GitHub Actions self-hosted runners because builds need to reach a private database or internal registry, or because the workload needs compute GitHub doesn't sell. The remaining reasons are that compliance requires the execution environment to sit inside a controlled boundary, or that the hosted queue has become the slowest part of the pipeline. Any of those justifies the move.

What doesn't justify it is a vague preference for owning the hardware. If your team has no capacity to own images and patching, hosted runners remain the safer choice. Public repositories are a harder line: GitHub recommends that self-hosted runners rarely be used with them, because untrusted pull request code can compromise the runner. Decide ownership first. The architecture follows from who carries the pager.

Threats to contain

A runner is a machine that downloads code from the internet and executes it with whatever credentials and network reach you gave it. GitHub's own documentation is blunt about what that means: self-hosted runners "can be persistently compromised by untrusted code in a workflow". Self-hosted runners expand the trust boundary because workflow code executes on infrastructure and network paths you control, and every control in this architecture exists to contain that.

The trust boundary is the workflow trigger. A push to main executes reviewed code. A pull_request from a fork executes code nobody has read yet, on the same fleet, unless you separate them deliberately.

Malicious workflow code

A contributor opens a pull request that modifies the workflow file or slips an unsanitized expression into a run block. On a persistent runner, the payload writes itself into a hidden directory and waits. Sysdig's threat research team documented exactly this pattern in the wild, with runner processes launched from paths like ~/.dev-env and runners registered under attacker-chosen names.

From there, the attacker inherits the next job's GITHUB_TOKEN and any secret a later job references. The attacker also inherits any network the host can see. Build outputs are the quieter risk. Code that alters a compiled artifact after tests pass leaves no failing check behind.

Supply chain compromise

In March 2025, an attacker rewrote the version tags of tj-actions/changed-files so that mutable references like @v45 pointed at malicious code that dumped runner memory into workflow logs. The action was used by more than 23,000 repositories, and CISA added the vulnerability to its Known Exploited Vulnerabilities catalog. Repositories that pinned to a commit SHA were unaffected. Forensics later narrowed confirmed secret exposure to 218 repositories, which is small comfort if yours is one of them.

Caches carry the same risk with less visibility. Adnan Khan, the researcher who named the technique, showed that a low-privilege workflow can flood the cache until eviction clears legitimate entries, then re-register those keys with poisoned ones. The release workflow restores them at full speed and publishes the result. On GitHub Actions self-hosted runners, a shared on-disk cache widens that path further.

Internal lateral movement

The reason you self-host is the reason a compromise hurts. A runner with a route to internal subnets and a long-lived cloud key is a beachhead with credentials. Block egress to the cloud metadata endpoint, because a job that reads node credentials inherits the whole node's role.

Scope matters too. When GitHub Actions self-hosted runners are registered at the organization level, GitHub schedules jobs from multiple repositories onto the same runner, so one careless repository defines the blast radius for all of them.

Reference architecture
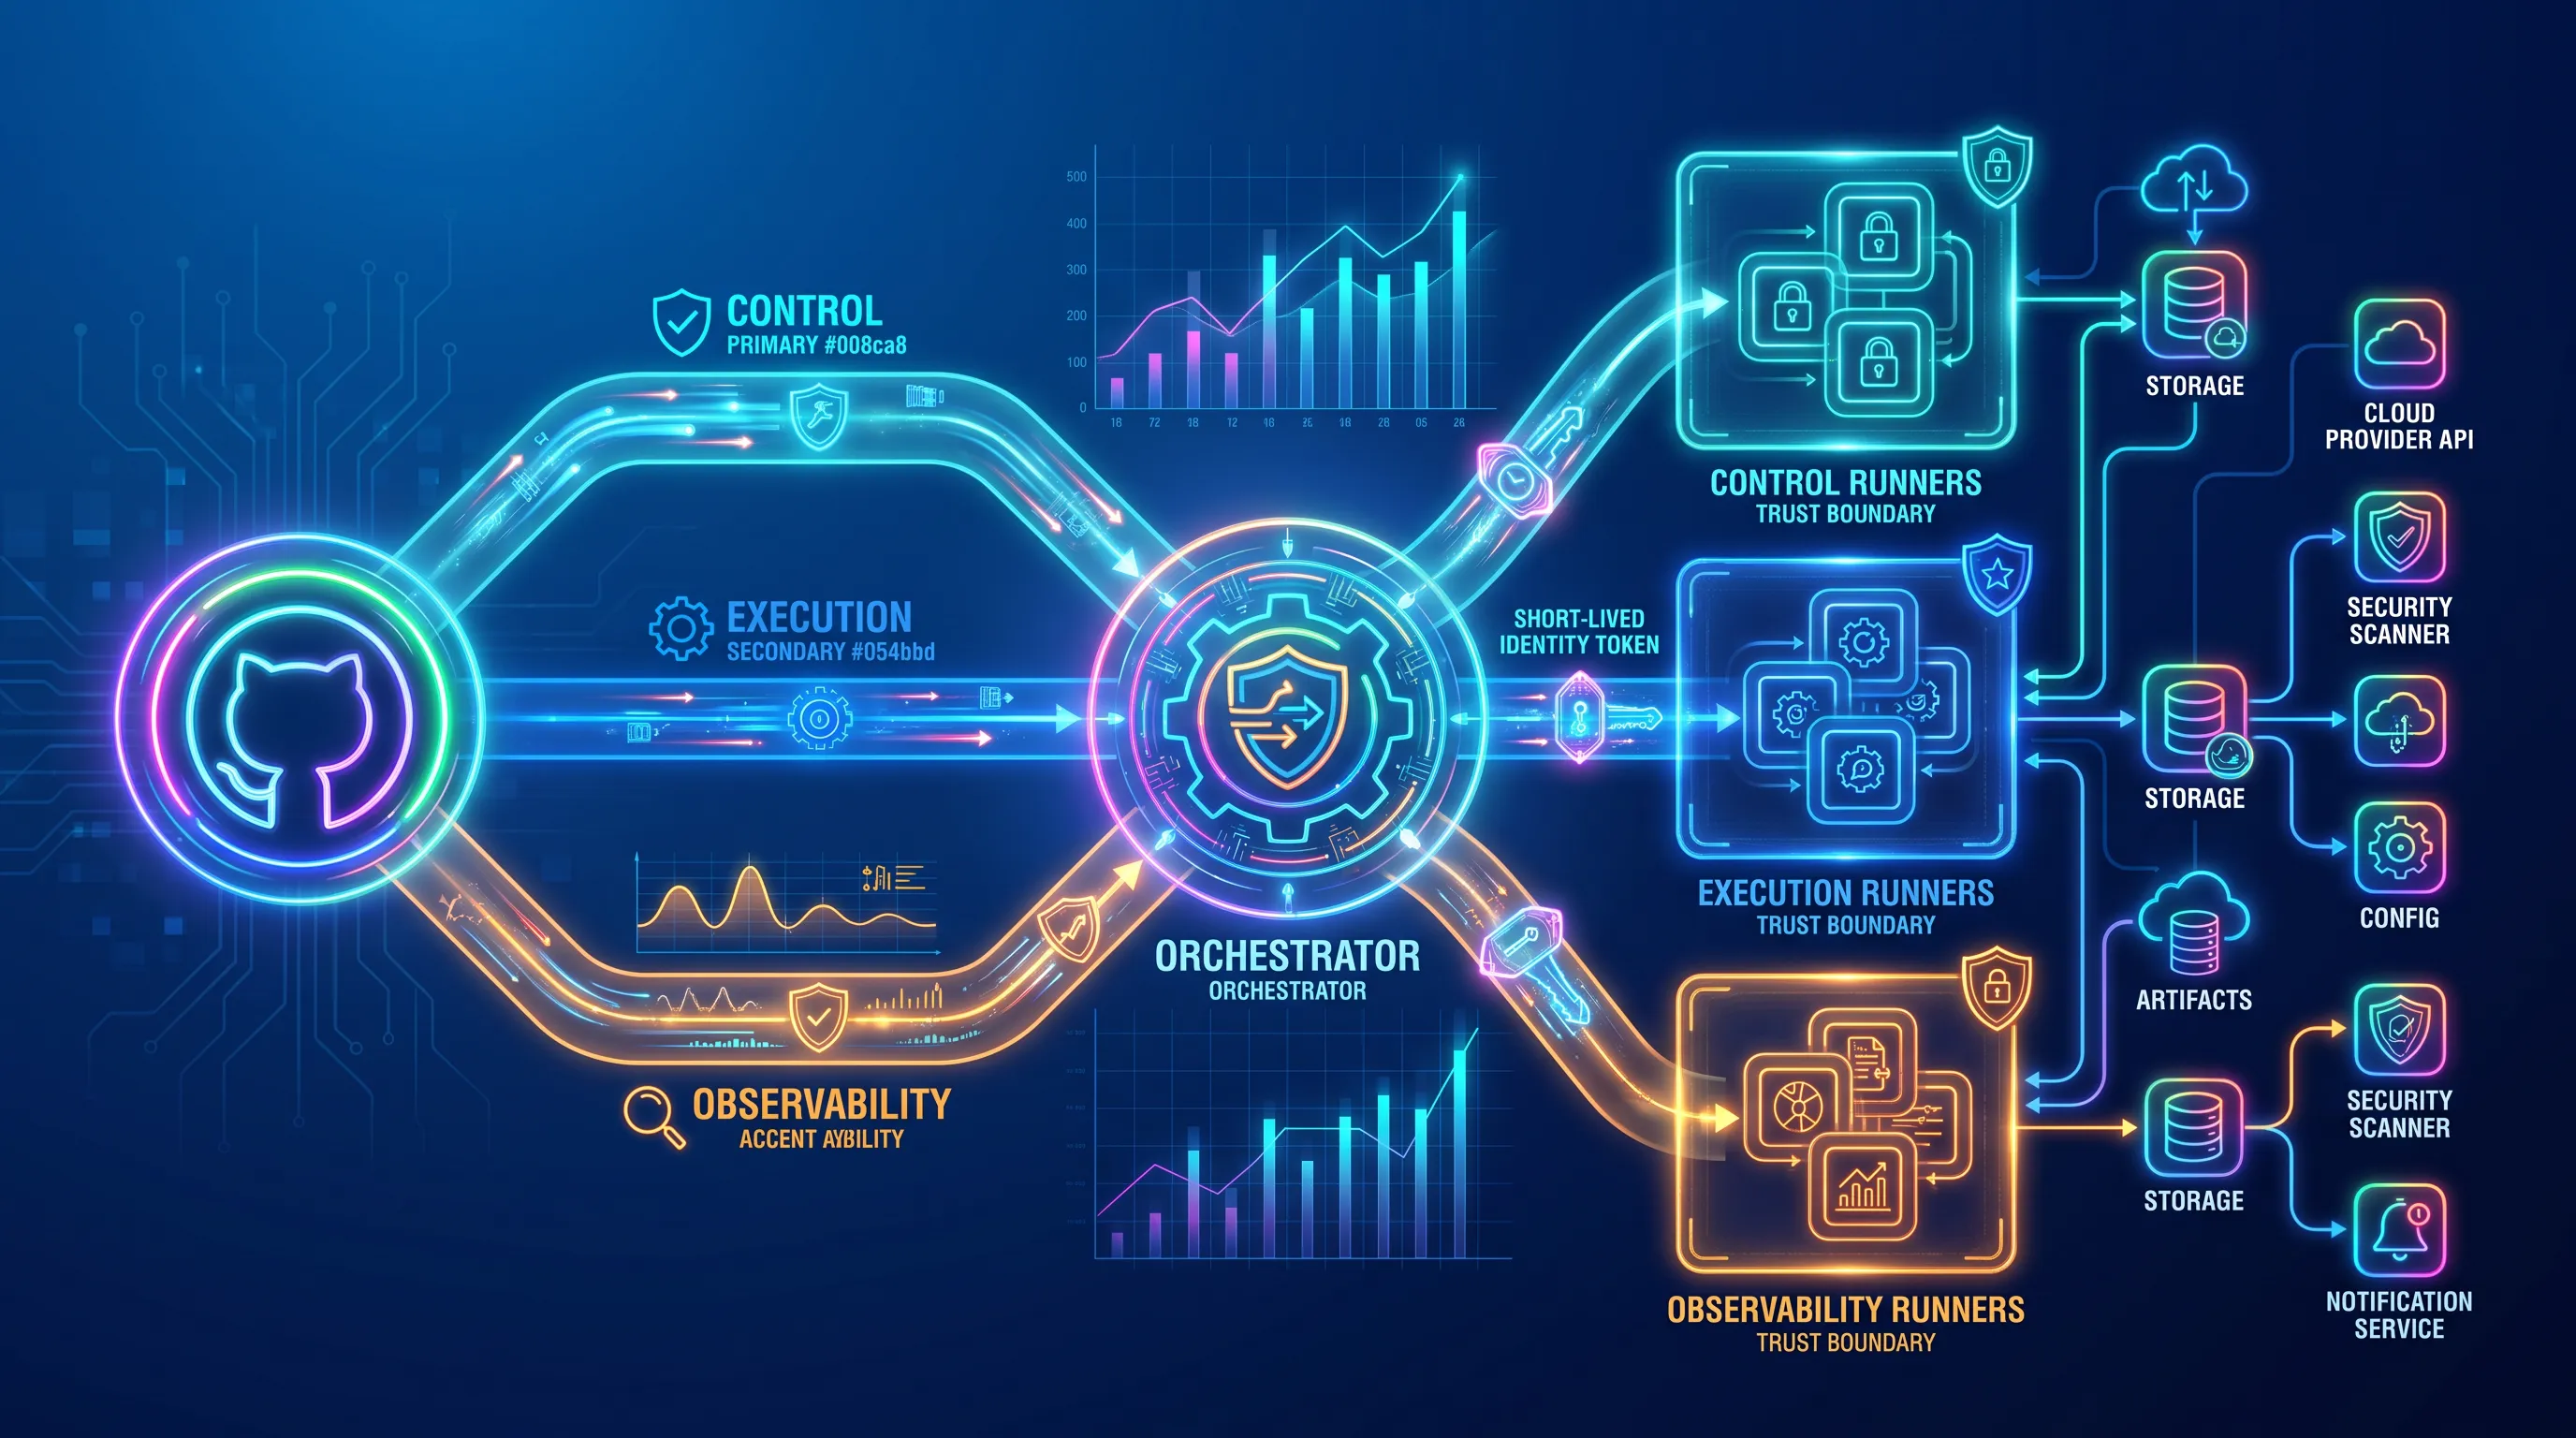
Vibrant neon hi-tech infographic illustrating a secure CI/CD architecture with glowing paths, icons, and digital elements on a deep blue background.

Separate three paths and the design mostly writes itself. The control path is GitHub talking to your orchestrator. The execution path is the runner doing work in an isolated subnet with allowlisted egress. The observability path ships logs and metrics off the runner to a store the runner cannot write to a second time.

Two principles sit underneath those paths. The first is that compute is ephemeral: one job per runner, then the host is destroyed. GitHub recommends ephemeral runners for autoscaling and discourages persistent runners in autoscaled fleets, so treat this as a baseline requirement rather than a scaling optimization. Second, identity is short-lived and federated, as the next section describes.

Caches and artifacts live in a remote store, scoped by trust level, because a shared disk defeats the point of destroying the host. Runner groups then decide which repositories reach which fleet, and for GitHub Actions self-hosted runners that group boundary is your first and cheapest containment control. The broader cloud DevOps operating model should reinforce those boundaries.

Need IT Support?

Book a free consultation with ABS Technologies experts we'll help you find the right managed IT, cloud, or security solution for your business.

Book a Free Consultation →

Workload identity over stored credentials

The most effective way to limit what a compromised runner can reach is to give the pipeline nothing durable to steal. Remove long-lived AWS, Azure, and GCP credentials from GitHub Actions entirely. With OpenID Connect (OIDC), a workflow can request a short-lived token from the cloud provider instead of holding a static key. The cloud side then decides whether to issue credentials based on the repository, workflow, branch or environment, and job context in the token's claims.

Design the trust policies so that a pull request validation job and a production deploy job can never assume the same role, and keep session durations to minutes. A stolen token then expires almost immediately, and a stolen static key does not.

Apply security controls

Controls belong in code. These are the ones worth arguing over:

  • Runner groups restricted to named repositories, with public repository access disabled and pull request validation kept on a separate fleet from deployment.

  • Ephemeral, single-job runners as the default for every fleet, with persistent runners treated as an exception that needs a documented owner.

  • A default permissions: contents: read at the workflow level, with write scopes granted only to the single job that needs them. The freeCodeCamp walkthrough of least-privilege token scopes is a reasonable starting table.

  • OIDC roles scoped per repository and per workflow, workflow, and branch or environment, with session duration measured in minutes and no static cloud keys stored as secrets.

  • Third-party actions pinned to commit SHAs, updated through Dependabot or Renovate so pinning doesn't become rot.

  • Cache namespaces split by trust level, since permissions: contents: read does not block cache writes.

  • Runner processes under a dedicated non-root user with no sudo rights, plus network policies that deny RFC1918 egress from untrusted jobs.

  • Default-deny egress with explicit destinations, rather than a blocklist of private ranges. The allowlist should cover only what the job needs, with deliberate controls around cloud metadata services, internal networks, management APIs, container and package registries, and other sensitive endpoints.

A hardened runner should not merely build software; it should produce verifiable artifacts. Generate an SBOM for each build, sign artifacts, record build provenance, and verify both at deployment so only artifacts built by an approved pipeline can ship.

Protected environments with required reviewers add a human gate before deployment credentials appear. They don't isolate execution, so treat them as approval. For additional information security guidance, keep those controls aligned with broader organizational policy.

Choose an autoscaling model

Compare models on isolation strength and startup latency. Virtual machine pools give the strongest isolation and the slowest cold start. Container-based pools start in seconds and depend on the kernel boundary holding. Whichever you pick, GitHub Actions runner autoscaling should be driven by the job queue rather than by a schedule someone tuned once in March.

The failure mode deserves as much design time as the happy path. A scaler that stops receiving queue signals either stalls every build or provisions until the budget alarm fires.

Ephemeral runner lifecycle

One job per runner, then the host is gone. This is one of the central recommendations of this architecture, and GitHub's guidance points the same way: use ephemeral runners when autoscaling, and avoid persistent runners in autoscaled fleets. GitHub's just-in-time registration API issues a configuration that runs at most one job before removal, which removes the registration token from your list of standing secrets.

Three things break this in practice. Images that drift from source control are one failure, and deregistration that fails and leaves orphaned runners collecting jobs is another. Logs that die with the host are the third. Ship logs and metrics off the machine before teardown, because on GitHub Actions self-hosted runners the deleted instance is also the deleted evidence.

GitHub Actions runner autoscaling

Queue depth is the input that matters. Scale-to-zero is correct for nightly or weekly workloads and wrong for a team that pushes every few minutes, where a small warm pool buys back the cold-start penalty on every single job. Put a concurrency cap on every scale set, because runaway scaling is a billing incident before it's an engineering one.

Cost guards belong in the same configuration as the scaling rules. Idle capacity is real spend, so set warm-pool sizes, scale-down timers, and concurrency caps deliberately and review them against actual queue data.

Need IT Support?

Book a free consultation with ABS Technologies experts we'll help you find the right managed IT, cloud, or security solution for your business.

Book a Free Consultation →

Kubernetes with ARC

Actions Runner Controller (ARC) fits when you already run Kubernetes in production and have someone who owns the cluster. It's a Kubernetes operator that creates runner scale sets which scale based on workflows running in your repository or organization. The listener long-polls GitHub for a job-available message and patches the ephemeral runner set so a fresh pod registers with a just-in-time token.

ARC does not remove the need for isolation. GitHub recommends isolating runner workloads from production workloads, and suggests separate namespaces for the runner and operator components. Treat the runner cluster or node pool as an untrusted tier, not as a neighbor of production services.

What ARC does not do is absorb your Kubernetes responsibilities. Pod security context and service account scoping stay with the platform team. Node-level isolation between untrusted jobs and storage classes for the work volume stays with them too. Cluster upgrades remain their responsibility. Standing up a cluster purely for GitHub Actions runner autoscaling adds a maintenance burden that exceeds the benefit.

Operate the fleet

Own the image. Build it from a Dockerfile or Packer template in version control and rebuild it on a schedule. Scan it on every build. GitHub raises minimum runner version requirements periodically, so if you disabled auto-update (you should have), version bumps become a tracked task rather than a surprise. If runner auto-update is disabled to preserve immutable images, runner version updates must become part of the image-build and patch-management process, a tracked task rather than a surprise.

Cache hygiene is operational work too. The default budget is 10 GB per repository with entries evicted by last access date, and since November 2025 admins can raise that limit for a charge.

Observability and SLOs

Treat the runner platform as a service with its own service-level objectives. At a minimum, monitor:

  • Queue time, from job requested to job started.

  • Provisioning latency, from scale-up decision to a registered runner.

  • Job failure rate, separating infrastructure failures from test failures.

  • Runner startup failures.

  • Active and idle runner counts.

  • Image age, so stale images surface before they become a vulnerability.

  • Failed OIDC token exchanges, which flag both misconfigured trust policies and probing.

ARC exposes runner and controller metrics, which makes much of this available without custom tooling. Retain runner and audit logs centrally, and write the incident runbook now. Quarantine the scale set and revoke the OIDC role, then rotate anything the fleet touched and rebuild from a known-good image.

Model cost and capacity

Per-minute rates are the least interesting number in the model. Add compute and storage for images and caches. Cache and artifact storage belong in the model, as do cross-zone and egress traffic, Kubernetes control plane and node overhead, and the engineering hours spent maintaining all of it.

Then add the two costs finance never sees. Idle capacity is the price of your warm pool, and it's knowable. Developer wait time is larger and harder, and the platform engineering figure of 5 to 10 hours per month lost to infrastructure friction per developer gives you a defensible starting estimate. Divide everything by successful jobs completed. Total cost per successful job is the one metric that makes GitHub Actions runner autoscaling decisions comparable across models. A broader cloud cost review can help keep those infrastructure variables visible.

Migrate persistent runners

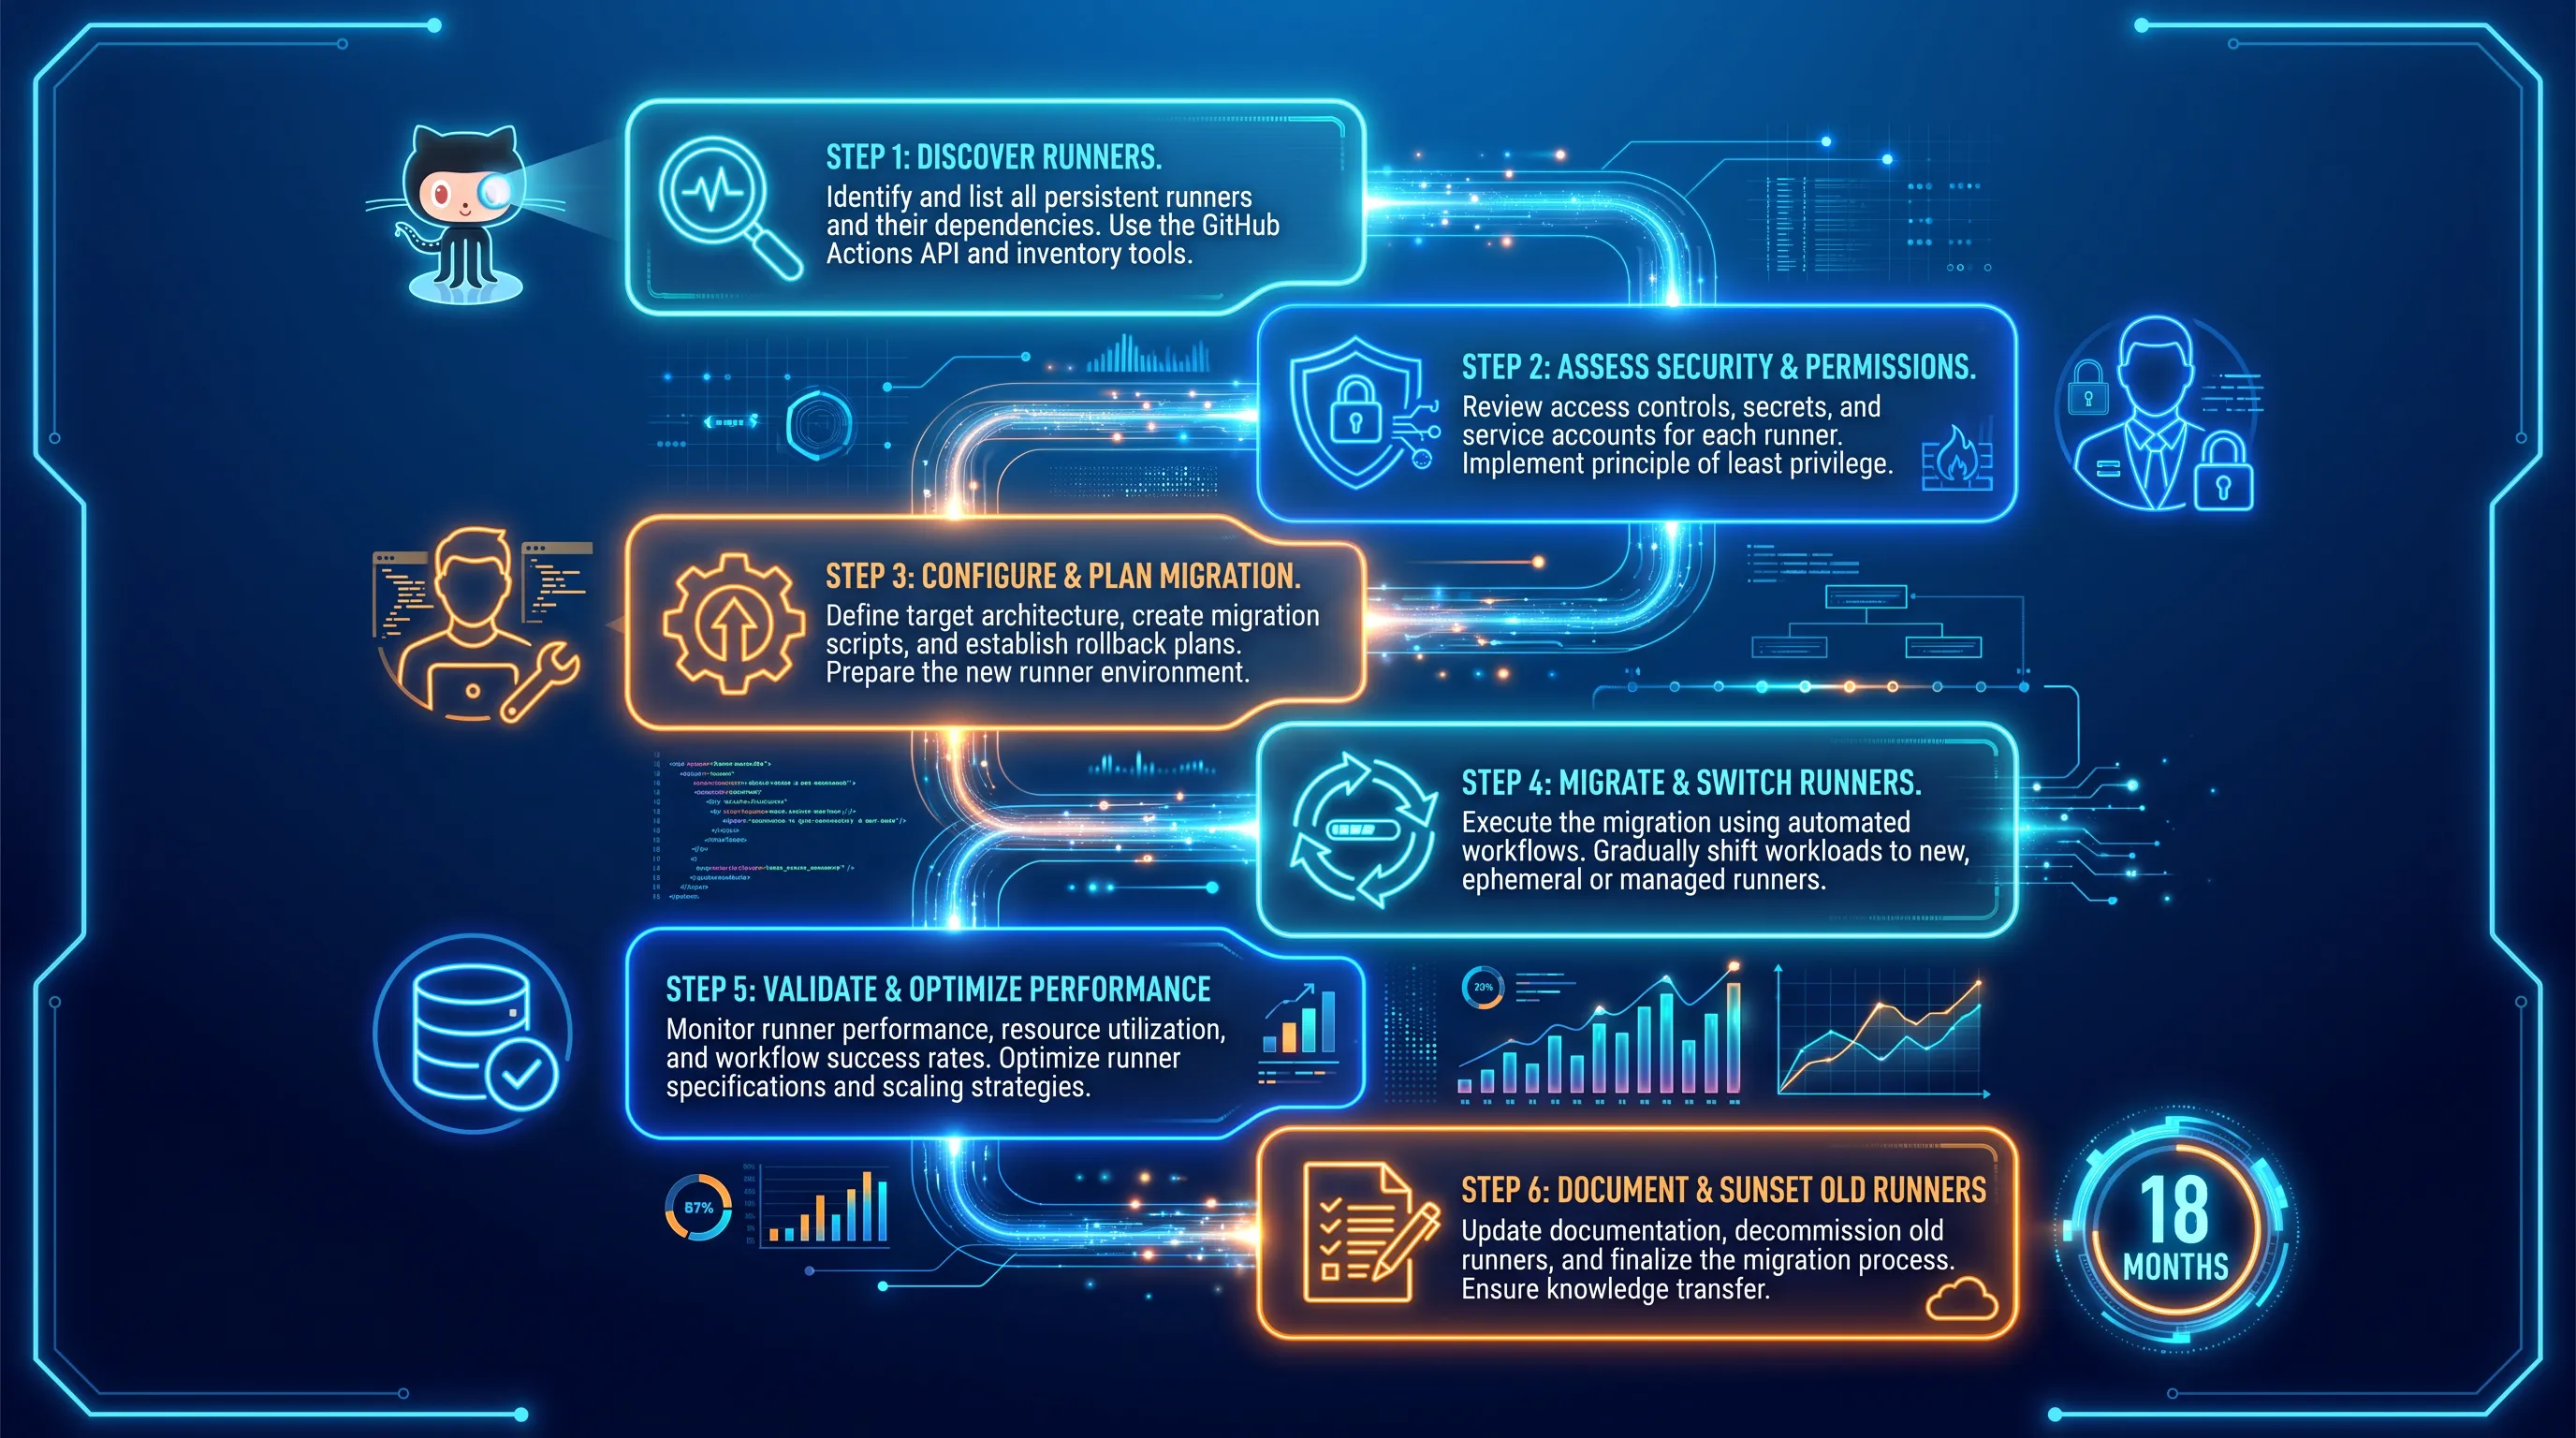
Neon hi-tech infographic depicting GitHub Actions migration steps with glowing panels, icons, and a deep blue gradient background.

Run the migration as a sequence:

  1. Inventory every workflow and its triggers. Inventory its secrets and its network dependencies. Flag anything using pull_request_target with a code checkout.

  2. Sort workloads into trust tiers and assign each tier a runner group. Untrusted pull request validation never shares a fleet with release.

  3. Build and scan the runner image, then pilot one ephemeral pool against a non-critical repository.

  4. Validate remote cache hit rates and OIDC credential exchange under real load, then test rollback to the old pool.

  5. Drain persistent runners rather than deleting them, and document who owns the image and the on-call rotation.

Expect cache hit rates to drop on the first pass. That's the honest cost of destroying the host, and it's why remote caching gets validated before you drain anything. Ownership documented at step five is what keeps GitHub Actions self-hosted runners from becoming an orphaned system eighteen months from now.

Confirm rollout readiness

Approval needs evidence: runner groups scoped and public access disabled, and token permissions minimized. Cloud credentials federated and actions pinned. Images owned and scanned, and cost per successful job measured before and after. Bring the rollback test results too.

What managed runner operations should include

Most of this work is ongoing rather than one-off, which is why many teams hand it to a managed provider. A managed runner service should cover:

  • Runner-image lifecycle: build, scan, and rebuild on a schedule.

  • Patching of images, runner versions, and the underlying hosts or clusters.

  • ARC or VM-pool autoscaling, with concurrency caps and warm-pool tuning.

  • OIDC design and trust policies for each cloud account.

  • Runner-group governance, including which repositories reach which fleet.

  • Network isolation with default-deny egress and reviewed allowlists.

  • Central logging, metrics, and SLO reporting for the runner platform.

  • Cost optimization, reported as cost per successful job.

  • Incident response, from quarantine through credential rotation and rebuild.

ABS Technologies builds and operates cloud and DevOps pipelines for software-led companies along with secure CI/CD architecture and infrastructure automation. If you're planning this work, reach out to our team for an architecture review or a migration-readiness assessment of your GitHub Actions self-hosted runners.

Need IT Support?

Book a free consultation with ABS Technologies experts we'll help you find the right managed IT, cloud, or security solution for your business.

Book a Free Consultation →

They can, but only on a separate, disposable fleet with no deployment secrets or private network routes. Use read-only permissions, block access to production systems, and require review before merging workflow changes. GitHub-hosted runners are safer when the workload doesn't require private connectivity.

Base it on measured concurrent jobs during the busiest interval, then add a small buffer tied to your queue-time target. Review the result against cloud quotas and the spending limit. Recalculate after changes in commit frequency, job duration, or workflow concurrency rather than keeping a fixed seasonal estimate.

Quarantine the instance immediately and remove it from scheduling before investigating the failure. Collect centralized logs, revoke related cloud roles, and destroy the host after evidence is preserved. Replace it with a fresh image instead of repairing it in place, since its final job state can't be trusted.

Ephemeral hosts reduce local residue, but remote caches still need trust boundaries. For github actions self hosted runners, use separate namespaces for untrusted validation and release jobs, restrict restore keys, and avoid restoring outputs created by lower-trust workflows. Monitor unexpected cache misses and changes in cache ownership.

ABS Technologies can review runner-group boundaries, workflow permissions, network routes, OIDC roles, image ownership, autoscaling limits, and rollback evidence. The review can also compare cost per successful job before and after the pilot. Teams can contact ABS through its contact page to discuss architecture or migration readiness.

Schedule a Meeting

Book a time that works best for you and let's discuss your project needs.

You Might Also Like

Discover more insights and articles

Industrial automation control system with connected electrical components and data infrastructure

Software Supply Chain Security: Controls That Protect Code from Commit to Production

Every step between a developer's commit and a running production workload is a place an attacker can intervene: a poisoned dependency, a tampered build, a stolen pipeline credential, an unsigned image. Mapping these attack paths end to end shows which control interrupts each one and where a single control covers several paths at once. Because funding every control at once is rarely possible, a ranking method then orders the work by the risk each control removes, so limited budgets go first to the gaps attackers are most likely to use.

Futuristic digital system with connected components and data flows representing document workflow automation

HashiCorp Vault Secrets Management: Architecture, Adoption, and Operational Reality

The real shift in secrets management comes from long-lived, standing credentials to workload identity that issues short-lived ones on demand. HashiCorp Vault secrets management is one route to that shift, but it fits only some environments. This guide lays out the difference: where Vault earns its operational cost, when a simpler managed store is the better call, and how to sequence adoption without a disruptive cutover.

Abstract digital infrastructure with connected data blocks representing a document management system and automated workflow

Grafana vs Datadog: Open Observability Stack or Managed Platform?

The real question comes down to which observability operating model fits your engineering capacity, architecture, reliability requirements, and telemetry economics. Here's how self-managed Grafana, Grafana Cloud, and Datadog compare on architecture and three-year cost, plus a repeatable scoring model for your own telemetry volumes and staffing, and a proof-of-concept structure to test the shortlist before you commit.

Title:
Containers and Orchestration: The Future of Scalable Apps

Meta description:
Read: How are containers redefining scalability? You learn to deploy code faster and cut server costs.

Article:
# C

Containers and Orchestration: The Future of Scalable Apps

Most teams adopt containers expecting speed and simplicity. What they get is Kubernetes in production. The DORA research is direct about what happens next: migrating workloads to flexible cloud infrastructure without changing how you operate them can be more harmful than staying in a traditional data center. This article is an operational guide to what happens after adoption.